Set model limits and prices
The model catalog tells Chetty how big each model is, what it costs and whether it reads images, and it decides which models the workspace offers.
Open the catalog
- Open Settings → Models.
- Search the catalog by provider, model ID or exec name.
- Select a model to edit its settings in the panel.
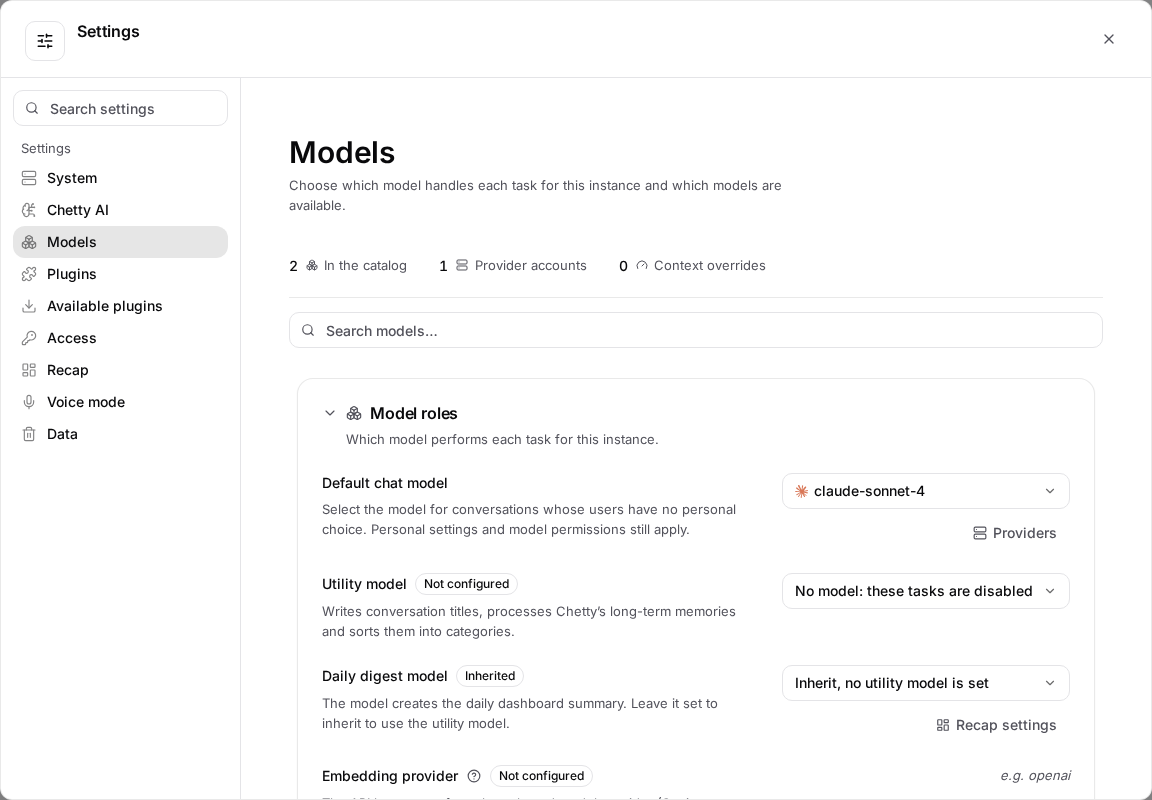
The list shows which models each provider offers and how many, so you can see at a glance what a provider brings.
What you can set
- Context window: how much conversation and prompt the model accepts.
- Maximum output tokens: how much the model may write in one reply.
- Accepts images: whether the model can read image turns.
- Prices per million tokens: input, output, cache read and cache write, in US dollars.
- Image resizing: maximum width and height, maximum encoded bytes, and JPEG quality for images stored in a conversation.
The provider or catalog rate is the default. An actual per-request charge reported by the provider still takes precedence over it.
Limits are per model pair
An override applies to the exact provider/model pair, so two providers that serve the same model name keep their own limits.
Chetty leaves room for the prompt when it applies an output limit. The default maximum output is 8,192 tokens unless the provider or an administrator supplies another value, and a limit larger than the context window is refused.
Model roles
Above the catalog, Model roles decides which model does what for the instance: the Default chat model every conversation starts from, the Utility model that writes titles and sorts memories, and the digest model that inherits the utility model unless you set one.
Read Model roles and per-model settings for the personal choices that sit beside these roles.
Admin: The catalog decides what the workspace offers. Each account still needs a grant, and a grant cannot make an unconfigured model run.